Exact, incremental sync
Bookmarks on every Health type find exactly the days that changed. Each one is sent whole, every type and source, so your receiver ends up with what the phone has, edits and deletions included.

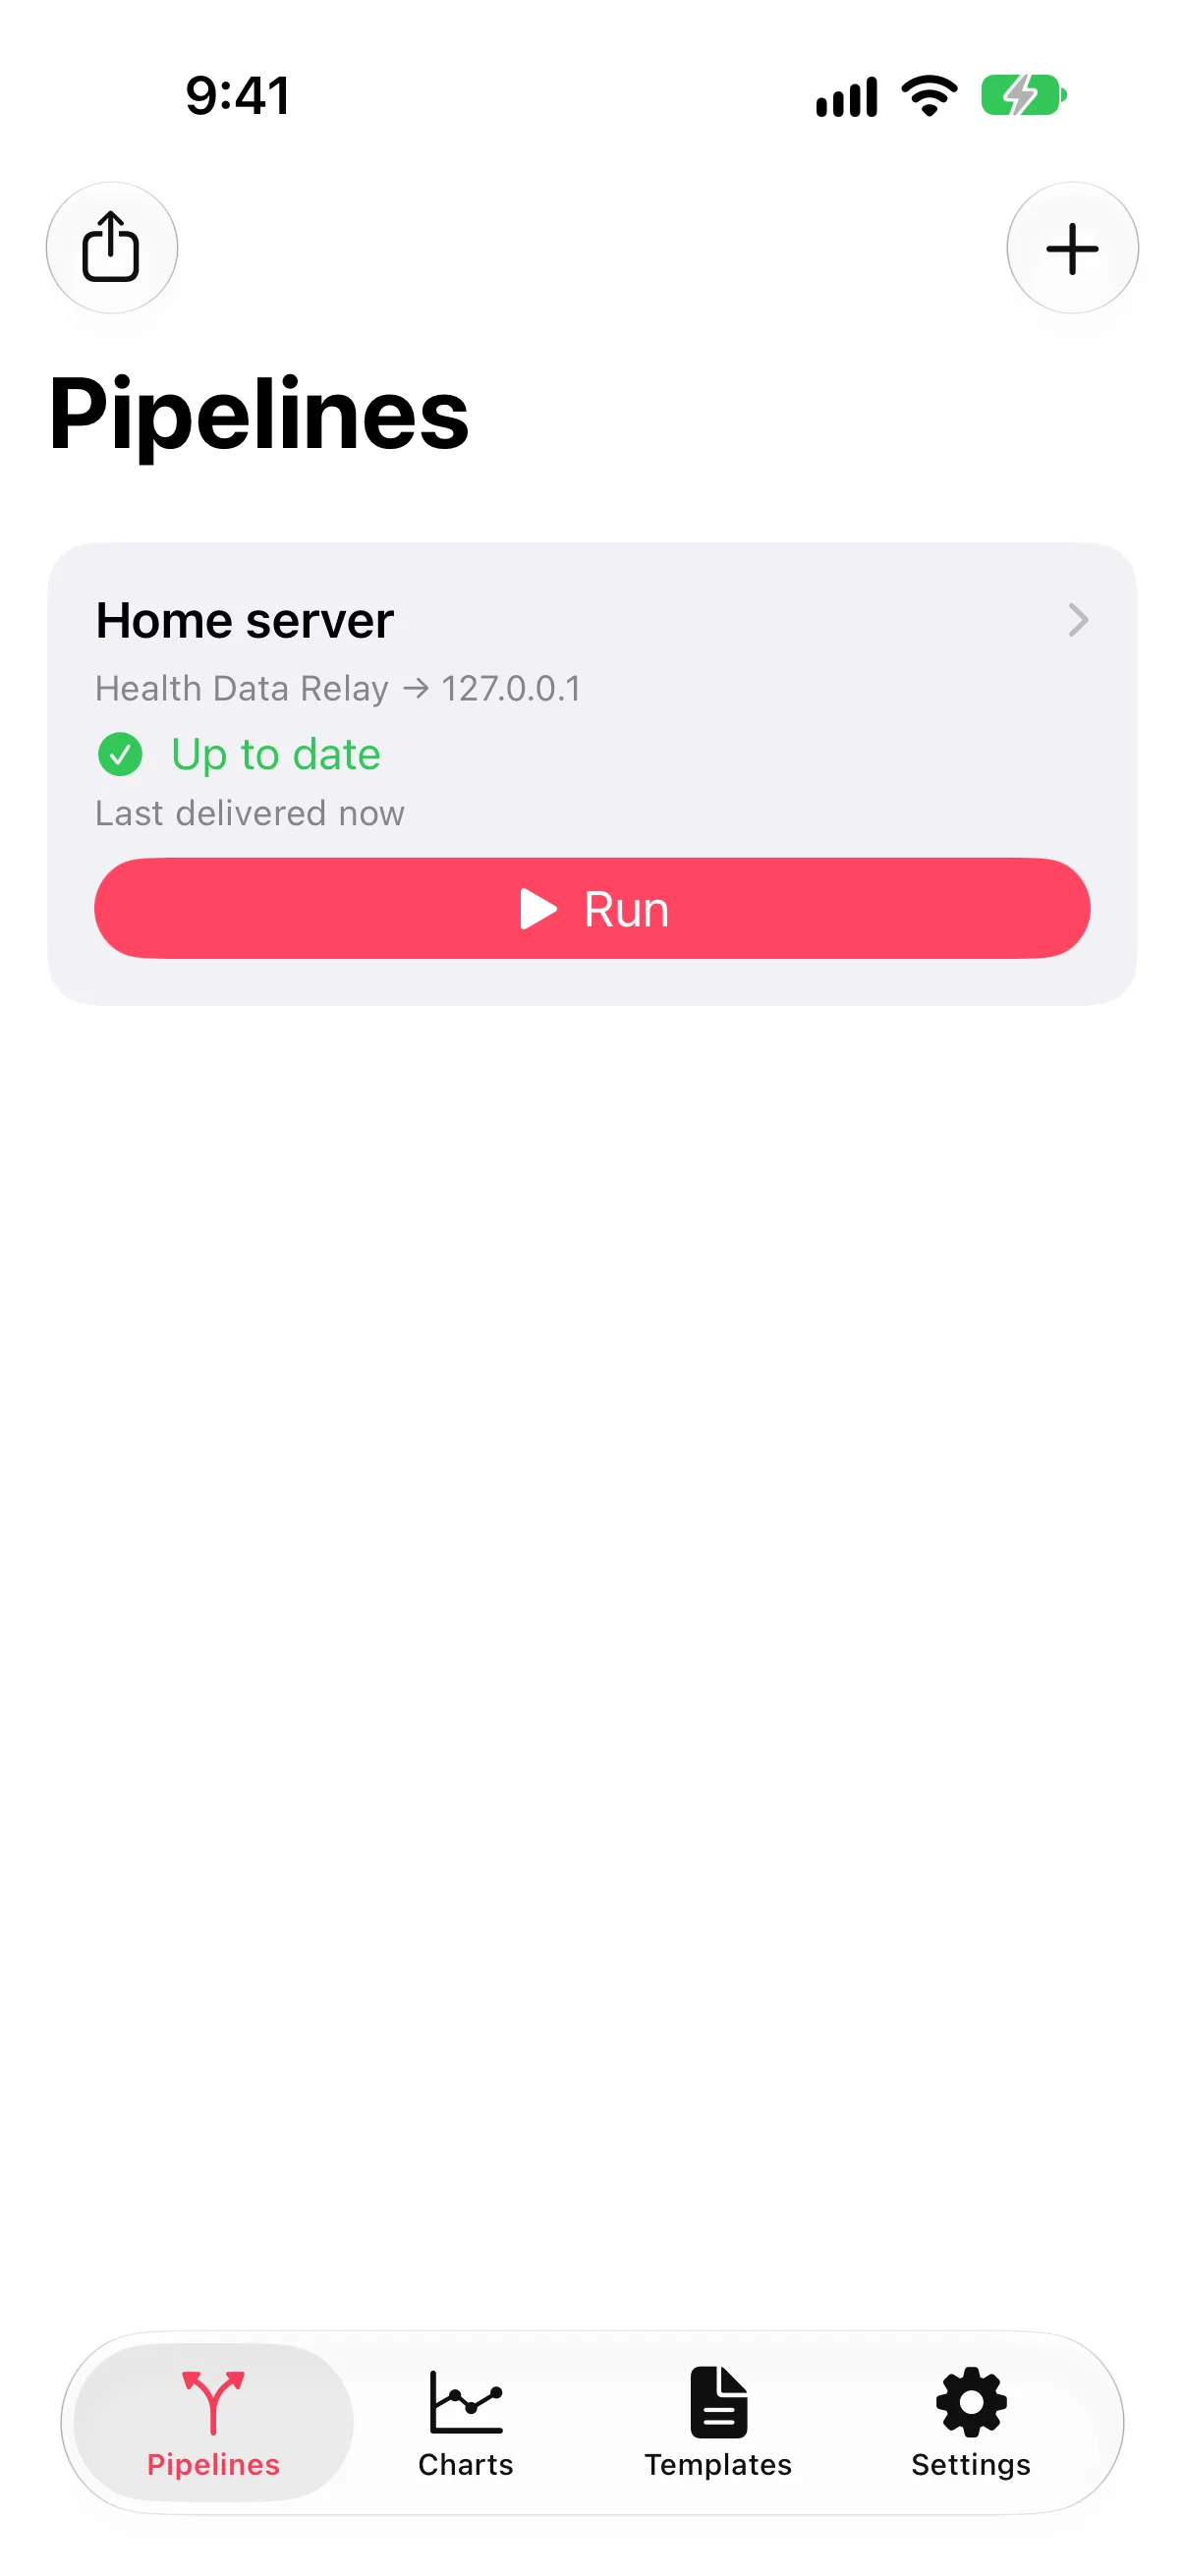
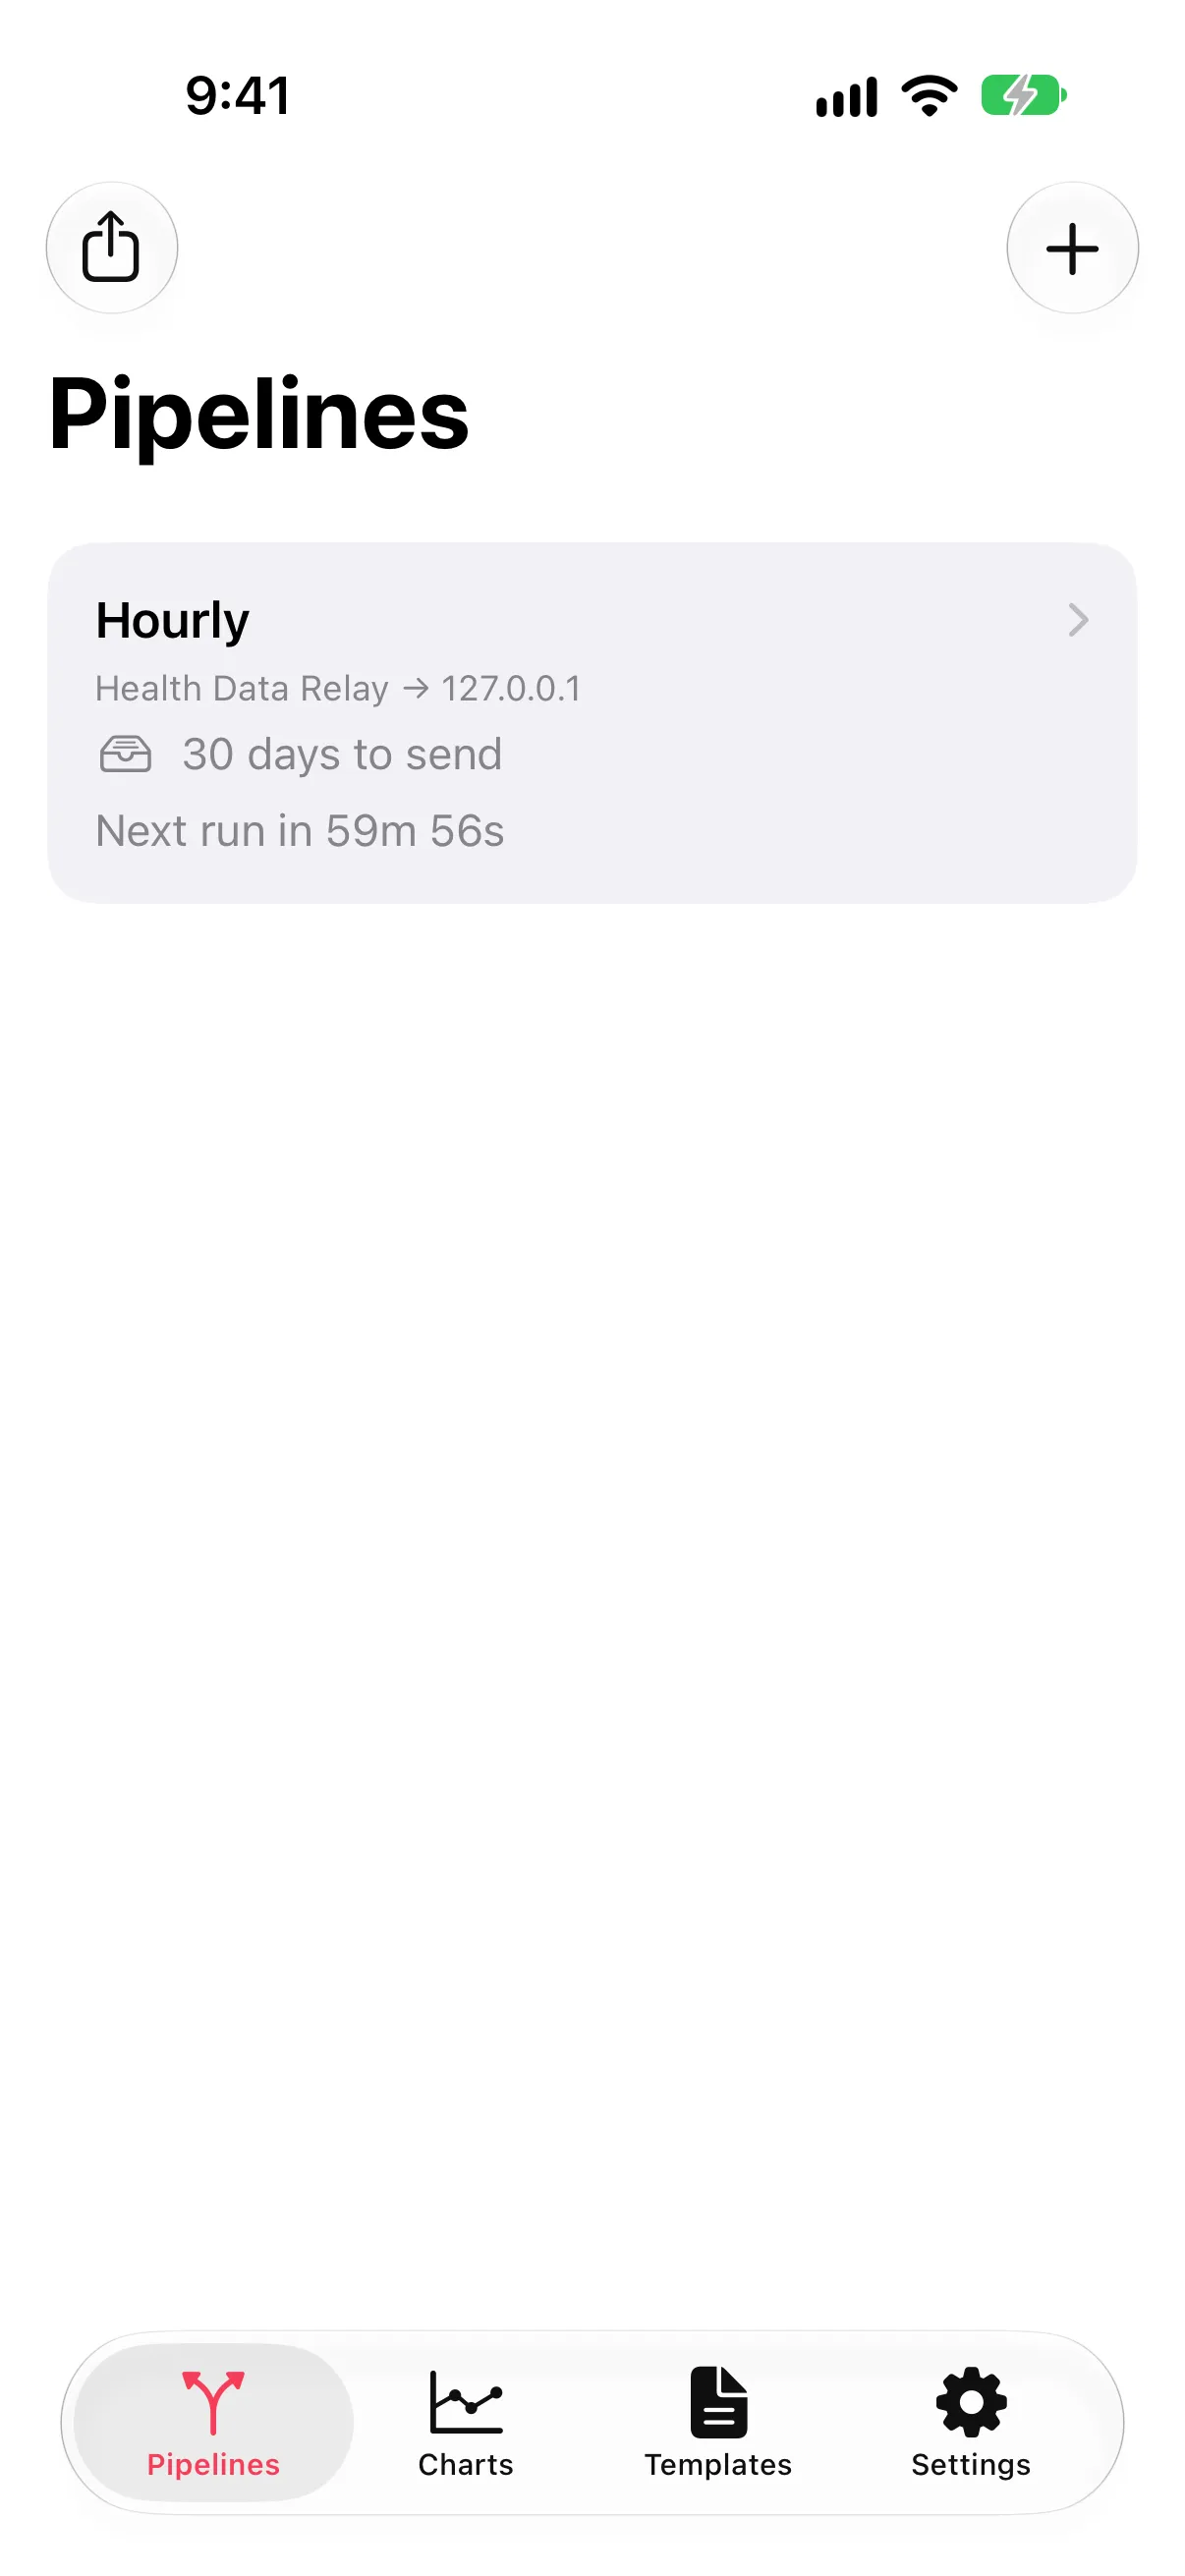
Apple Health has no cloud API. The only way your data leaves the phone is through an app on the phone, and the existing options pre-aggregate it, change their payload between versions, or sync when they feel like it. Health Data Relay does one job and does it exactly.
Exact, incremental sync
Bookmarks on every Health type find exactly the days that changed. Each one is sent whole, every type and source, so your receiver ends up with what the phone has, edits and deletions included.
One open schema
A single documented JSON format in Apple Health’s own terms, versioned by name. If you read
export.xml today, you already know it. Read the schema. Need another
shape? Templates write JSON, CSV, Markdown, GPX or your own format.
Destinations you choose
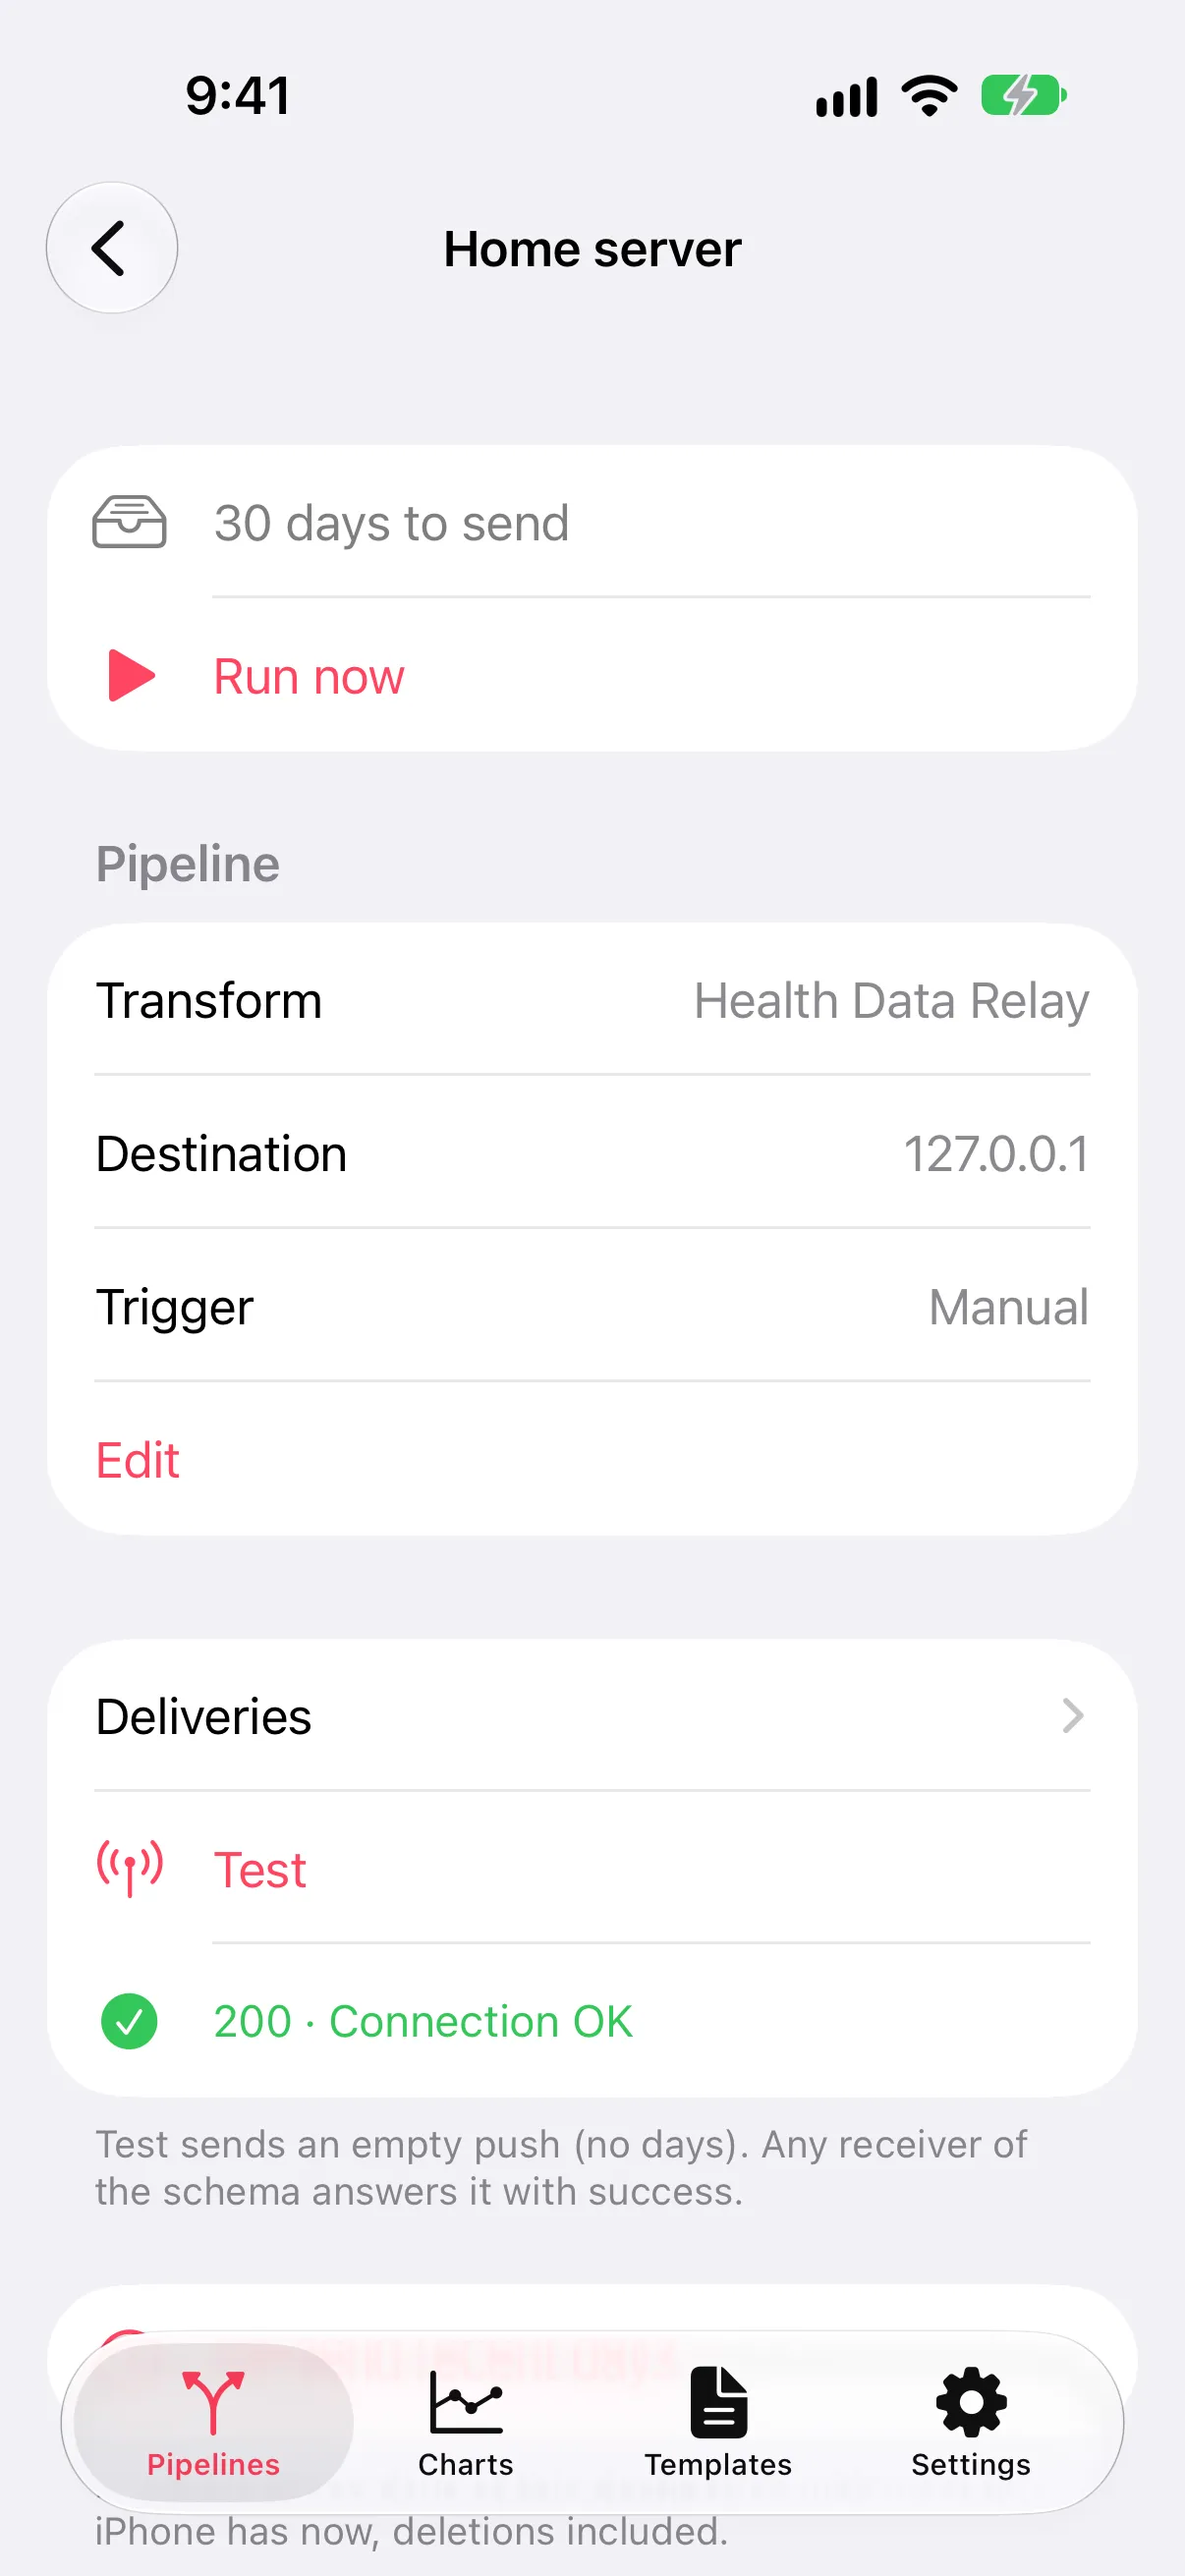
Any HTTP endpoint with an optional bearer token and headers, or, with a template, MQTT, email, your calendar, a folder or the share sheet. Each pipeline keeps its own place; one failing never holds up another.
Private by design
No account, no backend, no analytics. Data goes only to your destinations and the tools you turn on, and tokens live in the Keychain.
Runs when you say
Each pipeline runs when you tap Run, on a schedule, at a set time, or when Health records something. Unsent batches stay on disk and retry with backoff.
Per-source detail
Daily statistics per source (Watch, iPhone, scale, apps) plus the raw samples where they matter: sleep stages, blood pressure, workouts with routes, ECG traces.
Write a receiver in an afternoon: accept a POST, check a token, store the
days, answer 200. Writing a receiver has the
rules, and the repository includes a reference receiver and canonical
fixtures to test against.
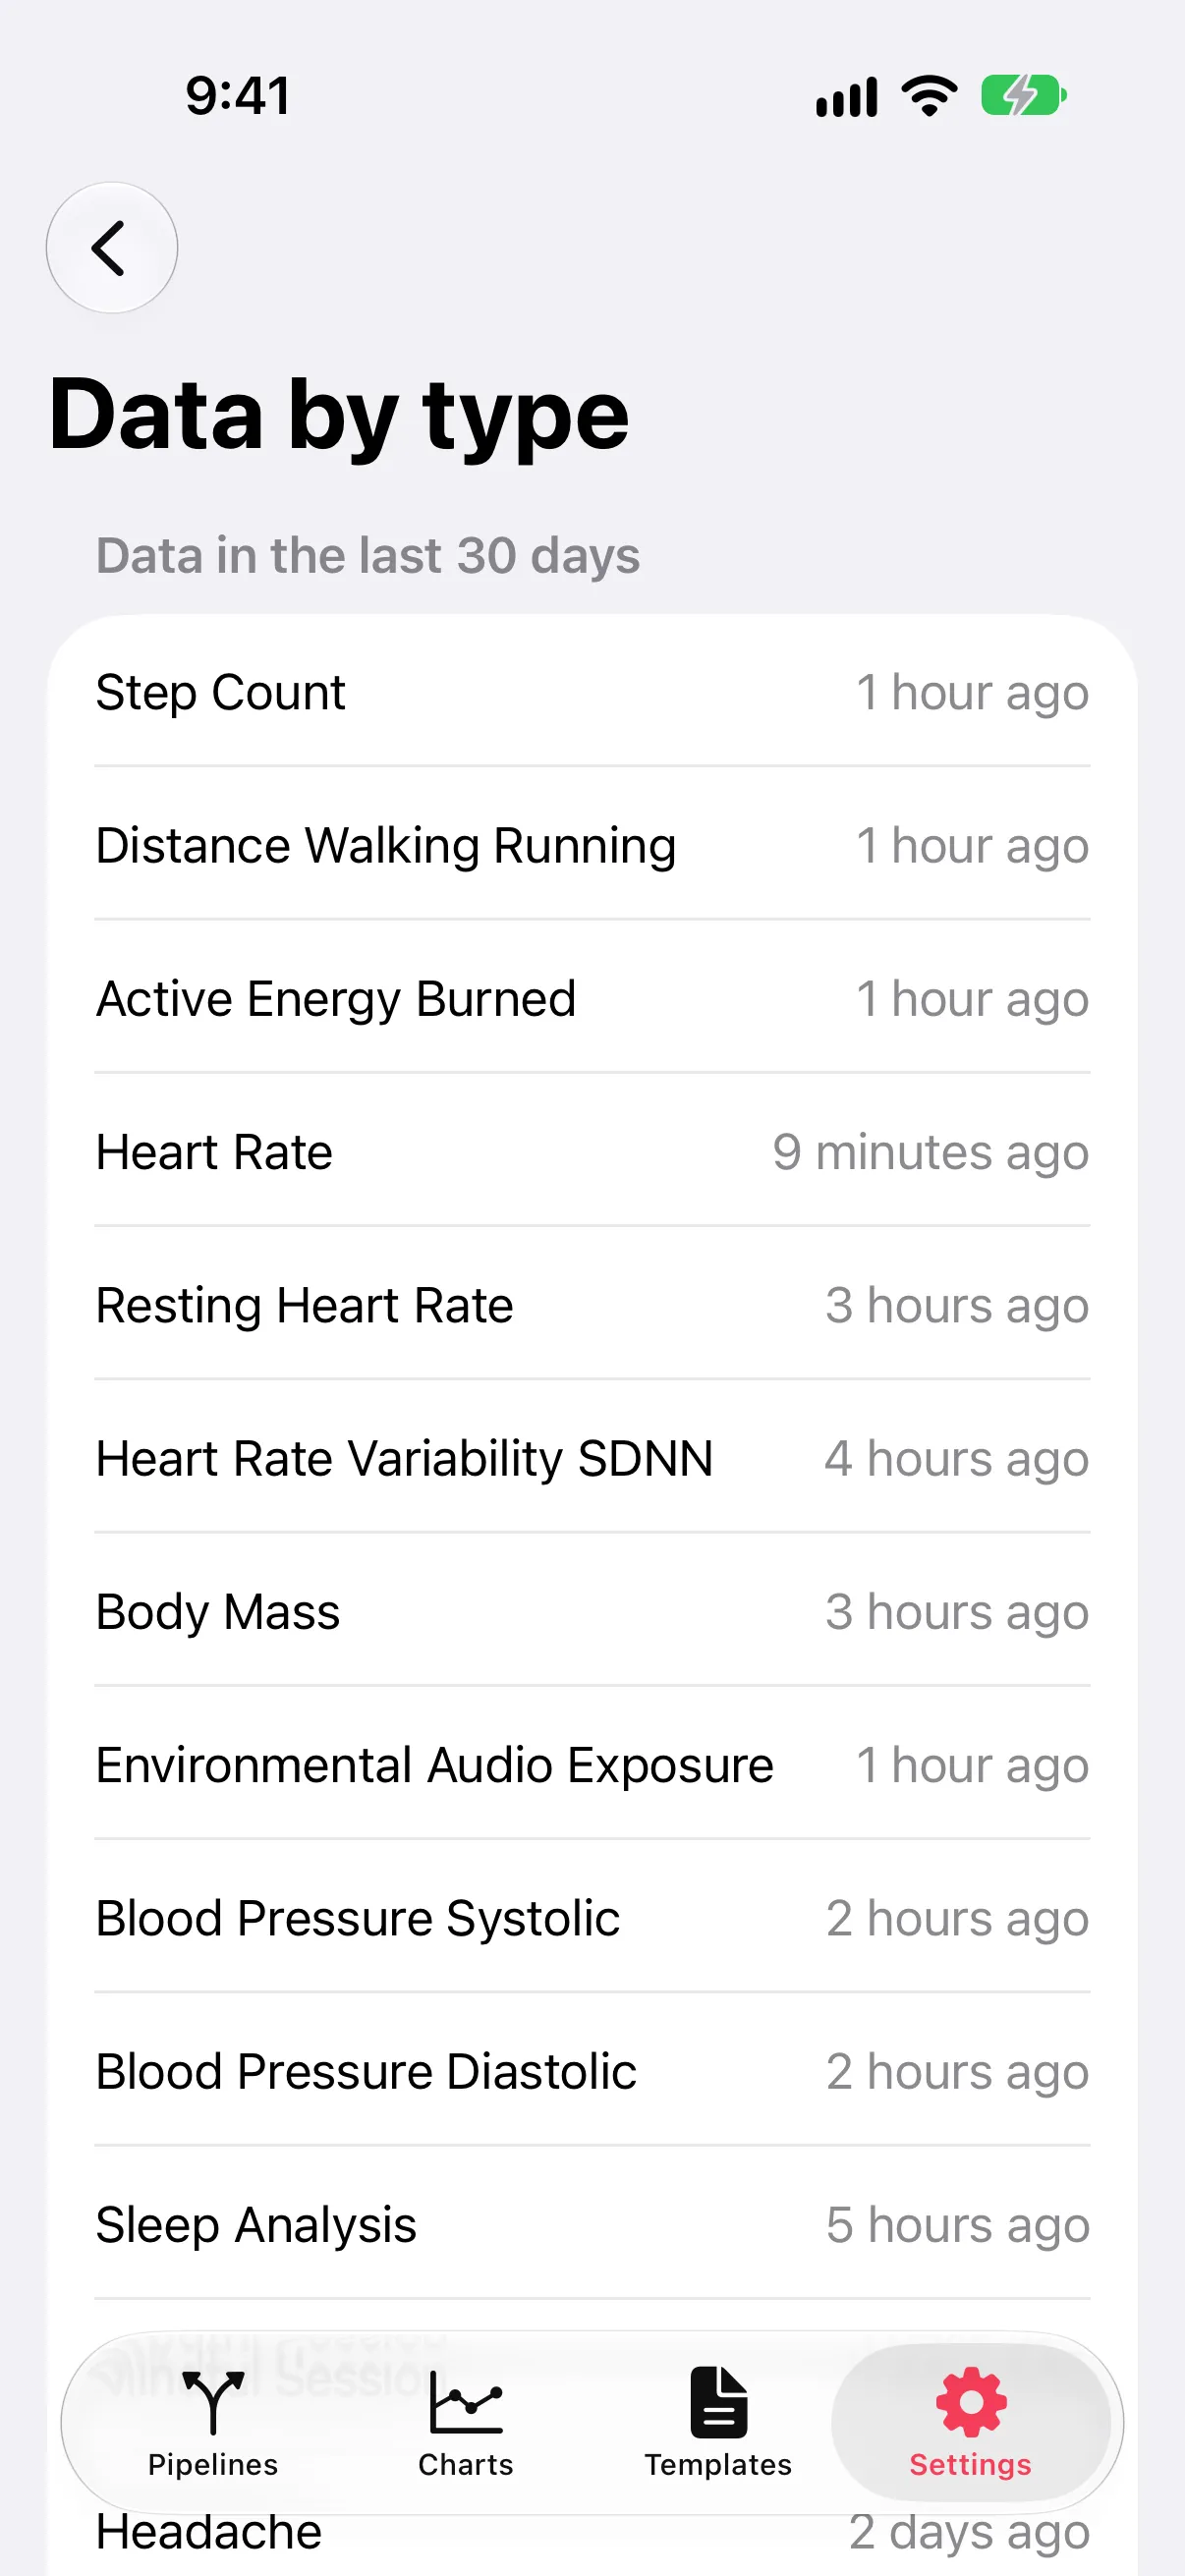
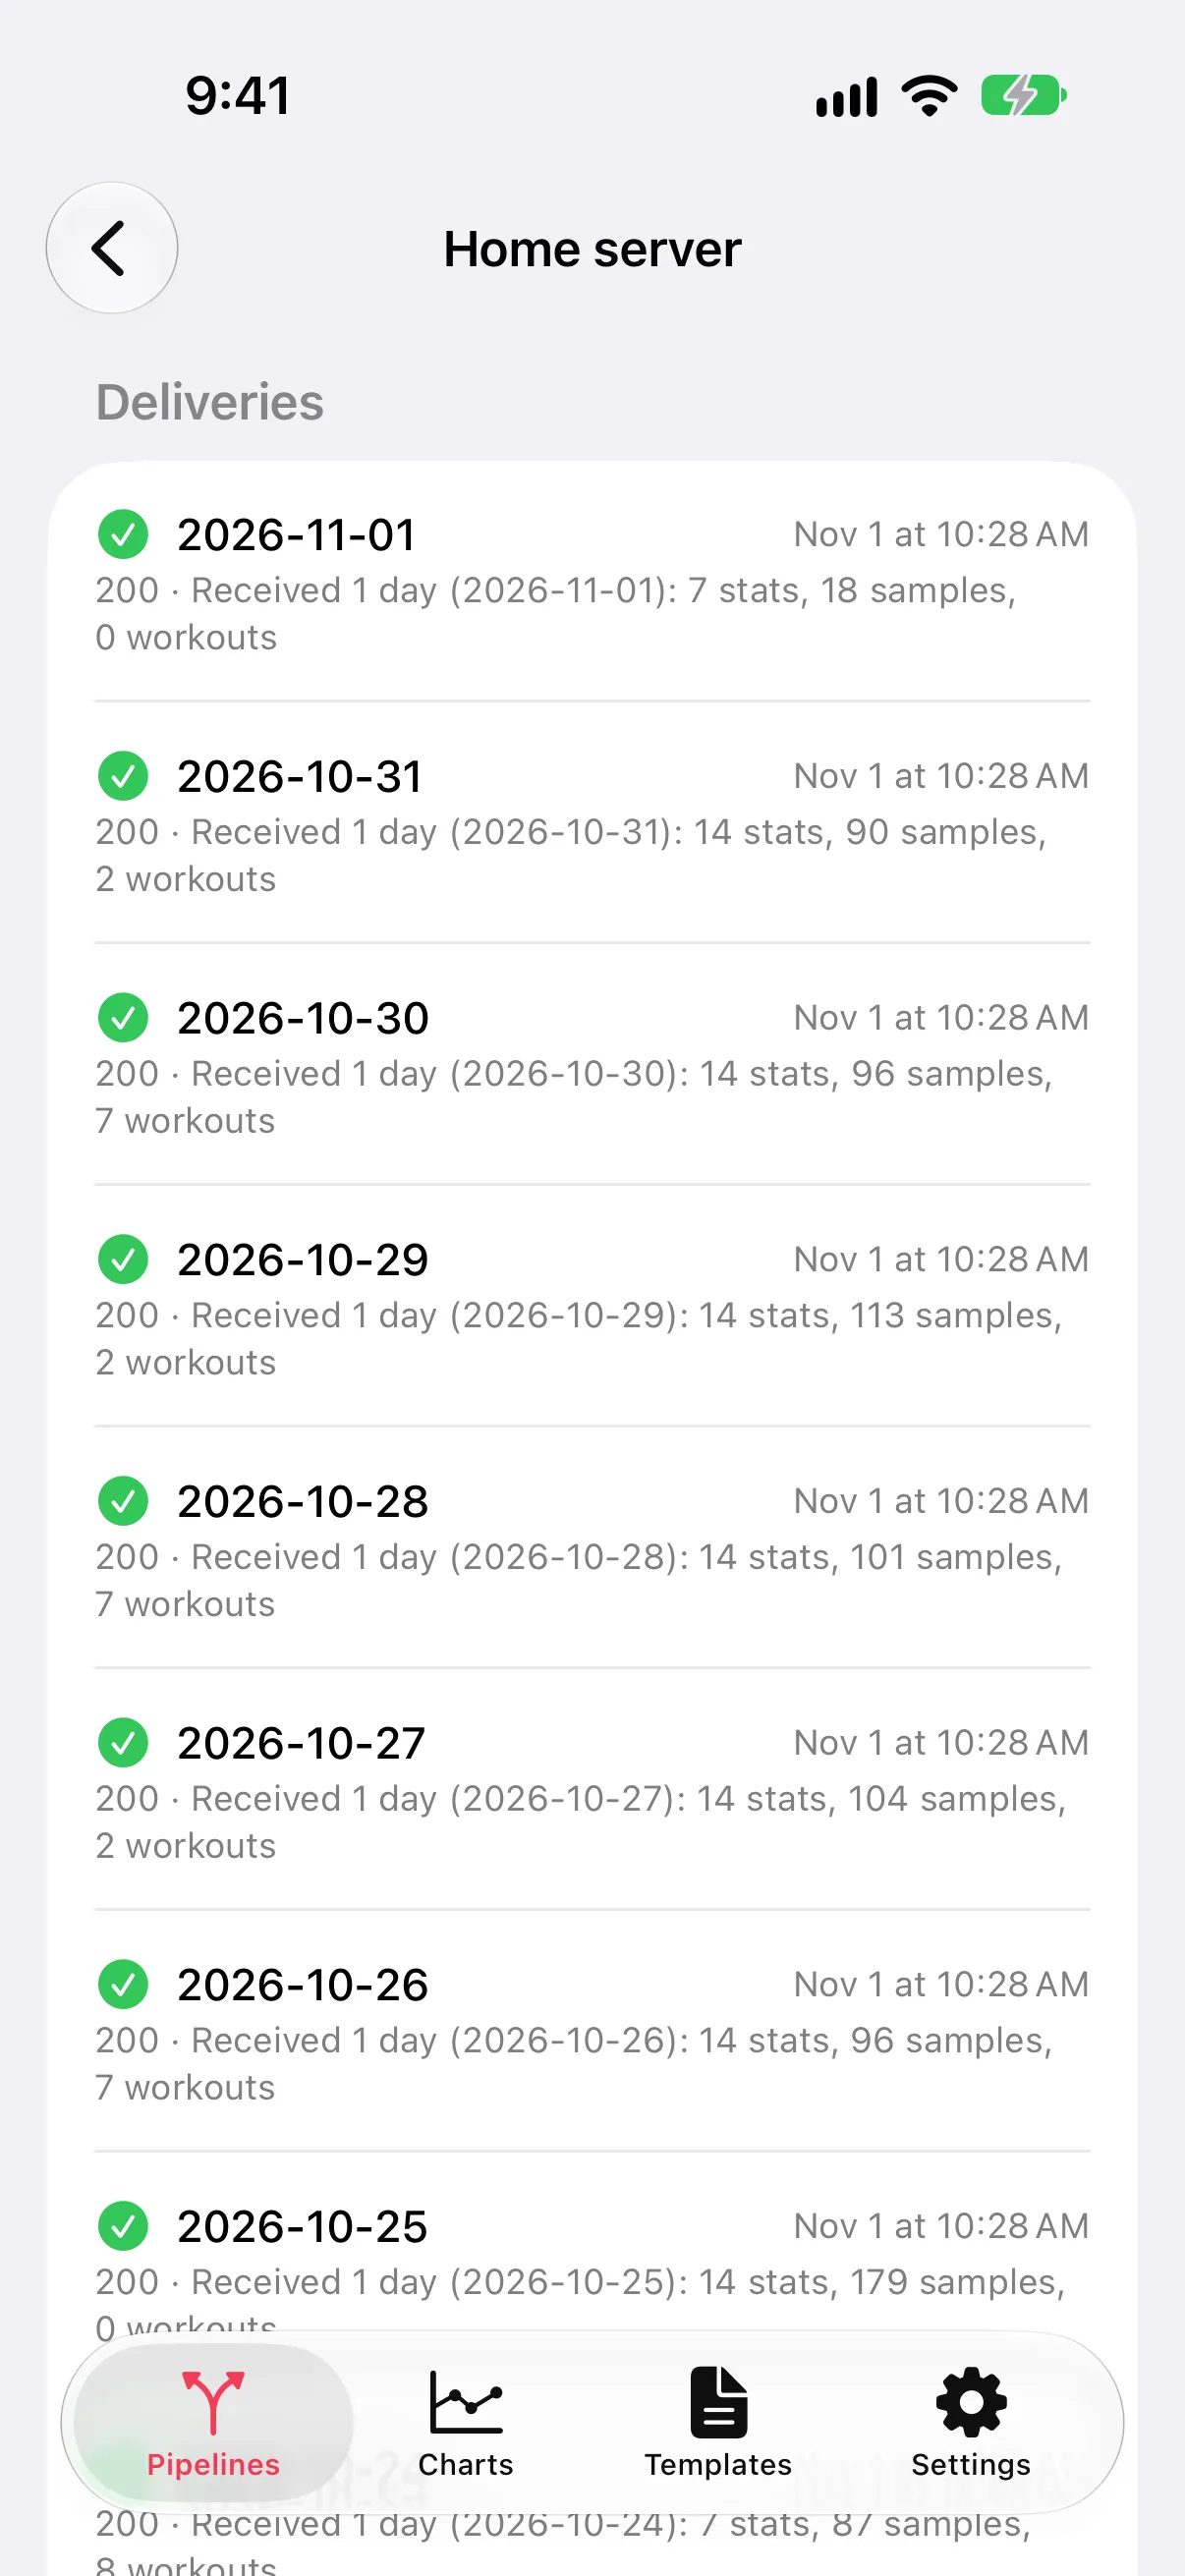
Every pipeline keeps a log of its deliveries with the receiver’s answer, and Data by type shows which Health types had data in the last 30 days, so a permission switched off in Settings is easy to spot.